

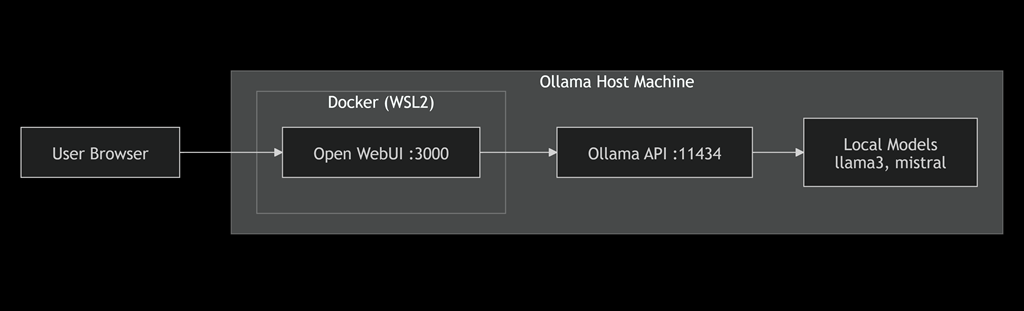
You can describe it like this:
- The user connects via browser to the host machine
- The request hits Open WebUI (running in Docker)
- Open WebUI calls the Ollama API on port 11434
- Ollama processes the request using local models
- The response flows back to the browser
Simple mental model
Browser → WebUI → Ollama → Model → Response
Set up Summary
Getting Ollama running on Windows
– How to install Linux on Windows with WSL

